

Blog

AI Coding Tool Adoption Doesn't Equal Value Delivered: Why Productivity Stalls and How to Fix It

AI coding tools usually aren't the problem. Adoption stalls when the tools land in workflows, repositories, and policies that nobody changed to use them. Stalled adoption looks like seats that are assigned but unused, or used heavily without changing how fast work ships.
How to Train Developers to Use AI Coding Assistants Effectively: A 4-Week Plan
Effective AI coding assistant training is structured practice on real work, not a tool overview or a one-day workshop. A four-week plan works well: two weeks of coached practice on a shared workflow, then two weeks applying that workflow to real backlog items, measured against a baseline.
What Is Spec-Driven Development? A Practical Guide for AI-Assisted Engineering Teams
Spec-driven development is a workflow in which engineers write a clear, reviewable specification before an AI coding assistant generates or changes code.
The First Agent Worth Running in Your Pipeline

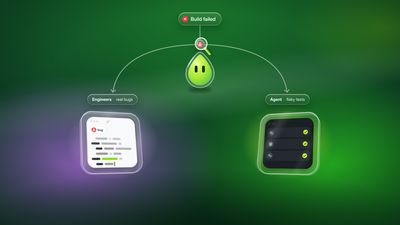
Pipeline-failure triage is a practical first job for an AI agent. Start with deterministic checks, then roll it out crawl-walk-run so the agent proves its diagnosis before it's allowed to change code.
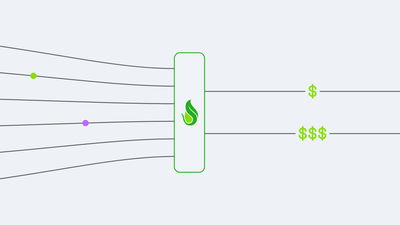
A Tuned vLLM Semantic Router Drastically Reduced Our Anthropic Bill

Liatrio benchmarked a tuned vLLM Semantic Router against Claude Opus and Sonnet on 62 agentic tasks. The router cut cost by about a third versus Opus alone, but solved nine fewer tasks (80 vs 89). Tuning took three rounds; results reflect work the router was tuned against, not a held-out test set.
Stop Measuring AI by Tokens. Measure It by Outcomes.

How Liatrio and SpaceXSI turn Grok, Cursor, and Grok Bot into enterprise throughput — with Forward Deployed Engineers who build with your teams, not for them.
Evaluating AI Systems Like Engineers, Not After the Fact

AI evaluation usually starts after something breaks. This post argues for engineering it instead: name failure modes first, run cheap checks before expensive judgment, and build the habits Liatrio teaches inside its AI Evaluation Bootcamp.
Silence Isn't Safety: What We Learned From Vetting AI Skills

What two months of building a vetting pipeline for AI skills taught us.
Five Scanners, 5,000+ AI Skills: What We Learned About Skill Security

Liatrio tested five AI skill scanners against real malicious and benign corpora. Static tools never beat a simple keyword grep. LLM-backed scanners (Snyk, Cisco, SkillSpector) scored far higher, and requiring three of them to agree gave the cleanest high-confidence results.
Tokens to Outcomes: Why Our Partnership With SpaceXSI is Different
Turn AI adoption into measurable business impact. Discover why Liatrio's partnership with SpaceXSI goes beyond faster coding by embedding AI into workflows, metrics, and operating models that scale across the enterprise. Read how we connect tokens to outcomes, not just usage.
Code Gauntlet Rewrite to Claude Workflows

We built a benchmark, measured our AI code reviewer against the market, then let Fable rewrite it over a four-day autonomous session. The new version tops every tool we scored.